Wentao Shangguan
Figure 1. Sampling xt = (1 − t) x0 + t ε, with ε ~ N(0, I), from t = 1 to 0. (a) Name. (b) Portrait.
PhD Candidate, ECE @ Boston University, advised by Prof. Vivek K. Goyal
I study statistics in generative models: diffusion guidance, posterior sampling and efficient LLM architectures.
Seeking 2027 research internships in generative models, world models and foundation models; start date flexible.
Research
Diffusion posterior sampling when the forward model is uncertain. An uncertainty-aware likelihood (UAL) keeps pretrained diffusion priors reliable under model mismatch [1].
Guidance for diffusion models. A noise-aware guidance schedule improves sample quality at no extra cost (23–30% lower FID on DiT-XL/2).
Efficient LLM architectures that share information across Transformer layers without reading from every layer.
Physics-guided adaptation. Adapted a frozen depth foundation model to a new infrared sensor without labels.
Before BU, I worked on neural video representations for frame interpolation (ECCV 2022) [3] with Prof. Ulugbek Kamilov in the Computational Imaging Group at Washington University in St. Louis.
Current work
-
Information Sharing Across Transformer Layers
Sep 2026 – present
Efficient LLM architectures that share information across Transformer layers without reading from every layer (in recent tests at 40M parameters, 8.9% lower held-out perplexity than a standard Transformer, and ahead of Kimi's Block Attention Residuals, published in 2026). Trained 40M-parameter, 48-layer decoder-only Transformers from scratch on about 200M FineWeb-Edu tokens.
-
Noise-Aware Classifier-Free Guidance
Sep 2026 – present
A noise-informed schedule for the guidance strength, with no extra training or network evaluations. On DiT-XL/2 with 50-step DDIM: 23–30% lower FID and 22–25% lower FD-DINOv2 than constant guidance at matched class accuracy. Also tested across step counts and on SiT flow models.
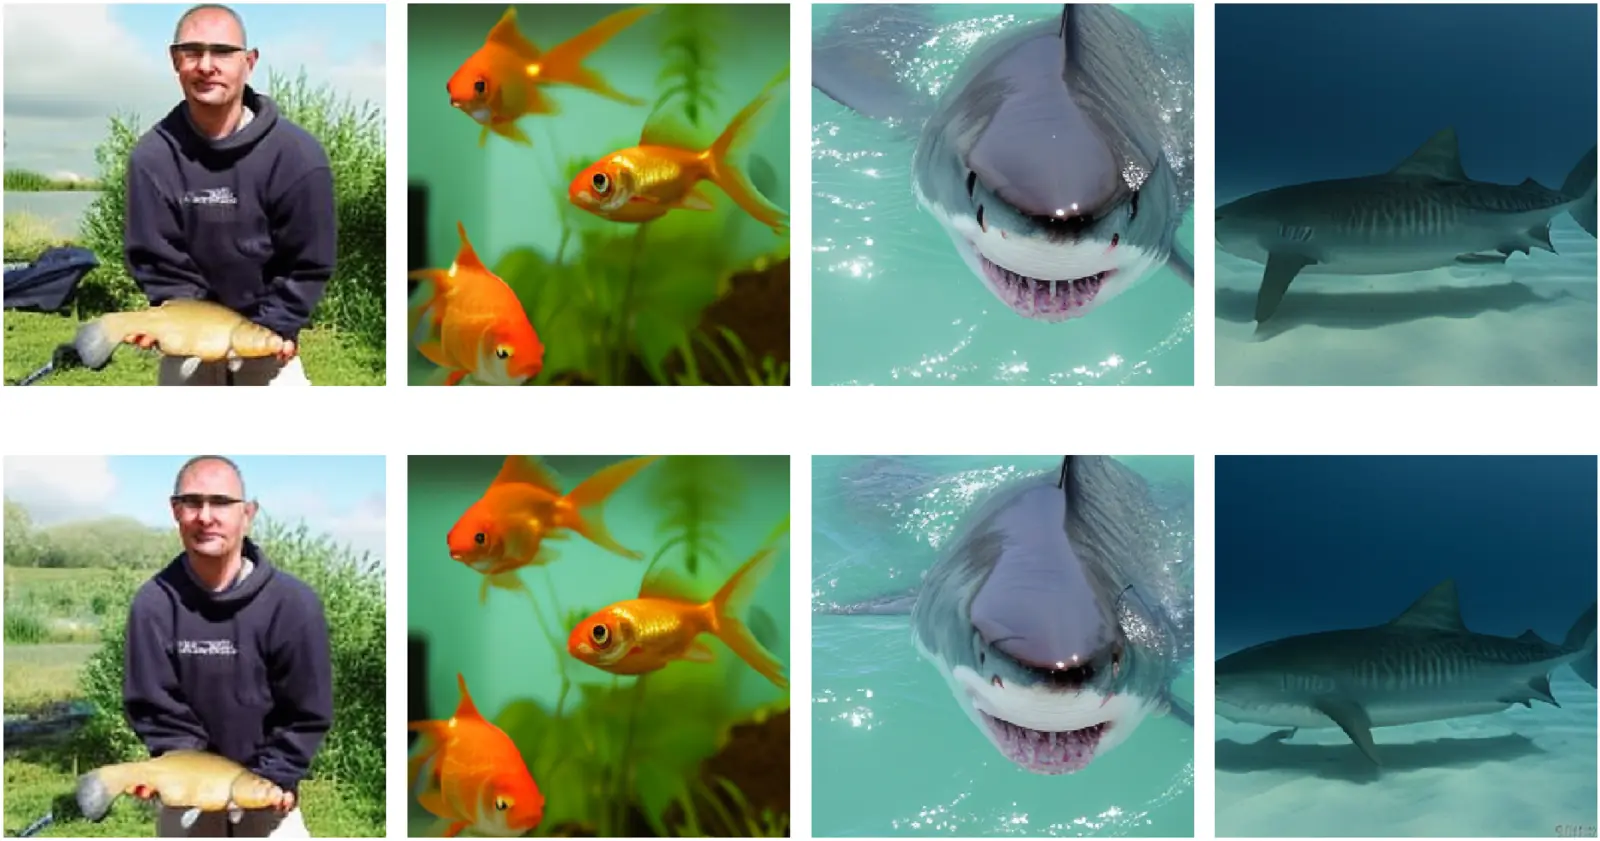
Figure 2. Class-conditional samples from the same seeds, with noise-aware guidance (top) and DG-CFG (bottom). -
Diffusion Posterior Sampling with Uncertain Forward Models (UAL)
May – Sep 2026
An uncertainty-aware likelihood that keeps pretrained diffusion priors reliable when the forward model is uncertain. Tested on six inverse problems (Gaussian and motion deblurring, CT, MRI, ultrasound and fluorescence microscopy), with better ensemble predictions (CRPS, energy and variogram scores). [1]
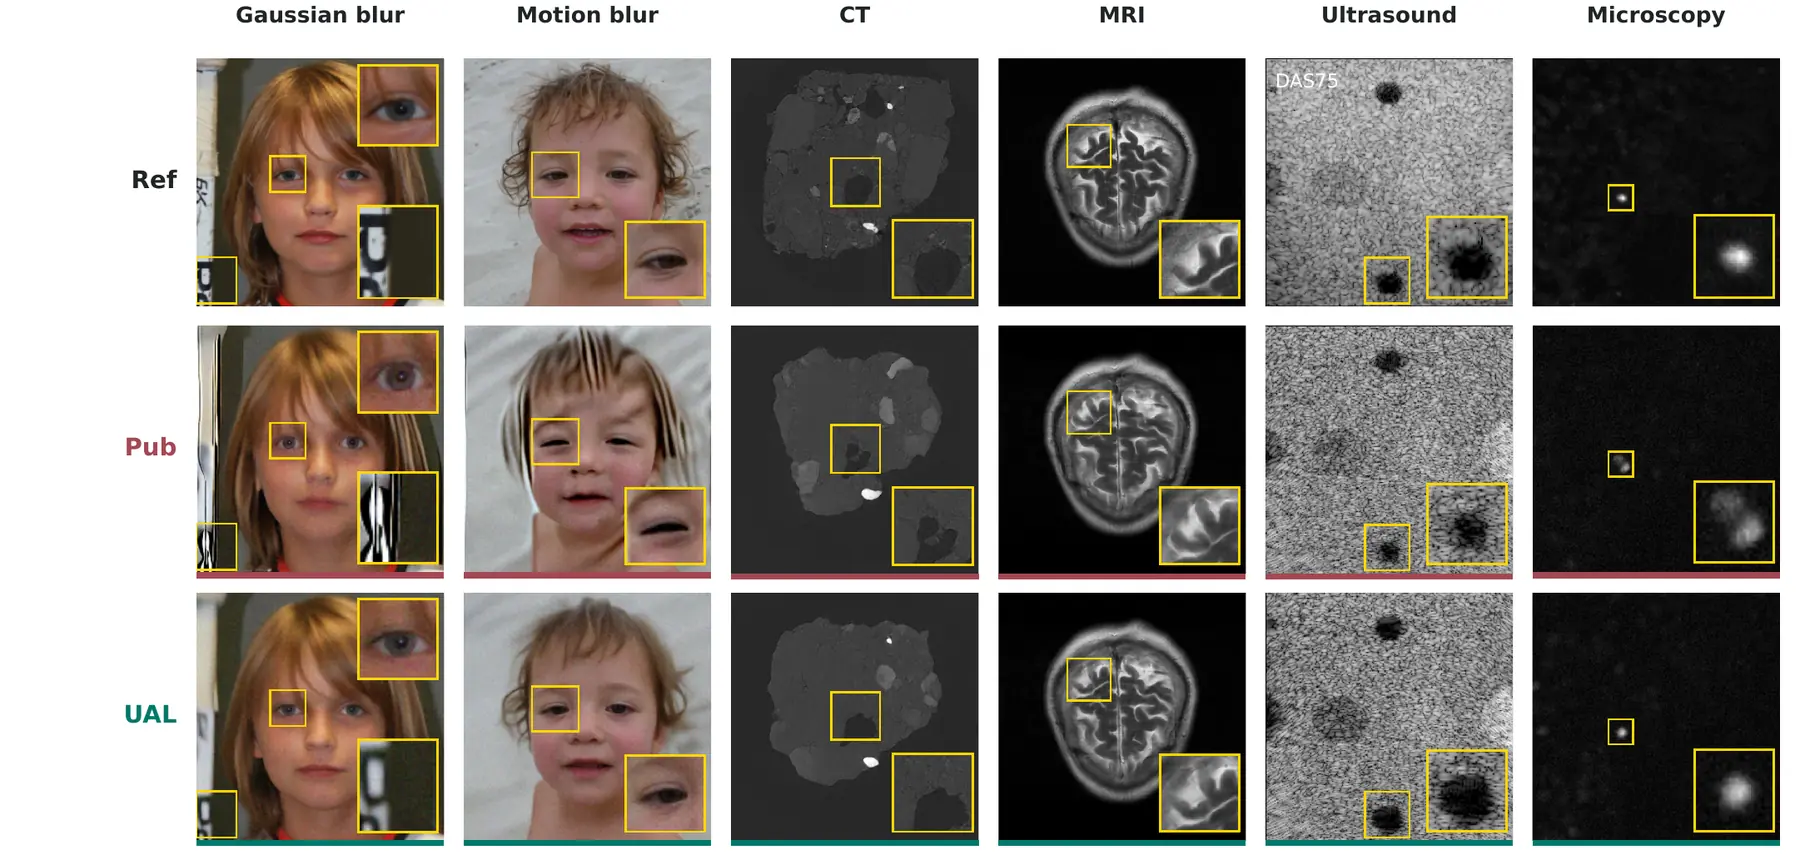
Figure 3. Results on six inverse problems, from the UAL preprint [1]. -
SpecDepth: Physics-Guided Reference-Free Adaptation of Depth Priors for Hyperspectral LWIR Ranging
Nov 2023 – May 2026
Adapts a frozen DINOv2-DPT metric-depth model to a 49-band passive LWIR hyperspectral cube without depth labels, lidar, stereo or RGB. The model predicts depth, temperature and per-band emissivity and is coupled to a differentiable radiative-transfer renderer; lidar is used only for held-out evaluation.
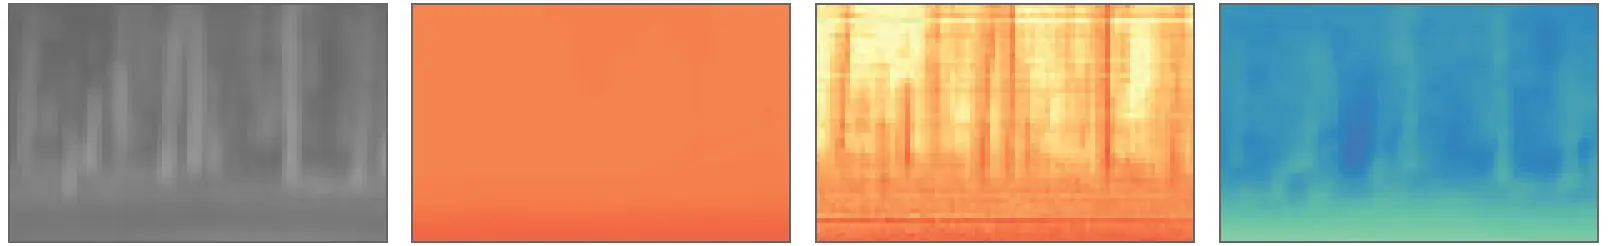
Figure 4. A distant forest background. From left: the broadband LWIR image, then depth maps from UniDepth-V2, physics inversion and SpecDepth (colour shows depth).
Publications
- [1]
-
[2]
Ozone Cues Mitigate Reflected Downwelling Radiance in LWIR Absorption-Based Ranging
IEEE Transactions on Computational Imaging, vol. 12, pp. 587–600, 2026. Selected for presentation at IEEE ICIP 2026.
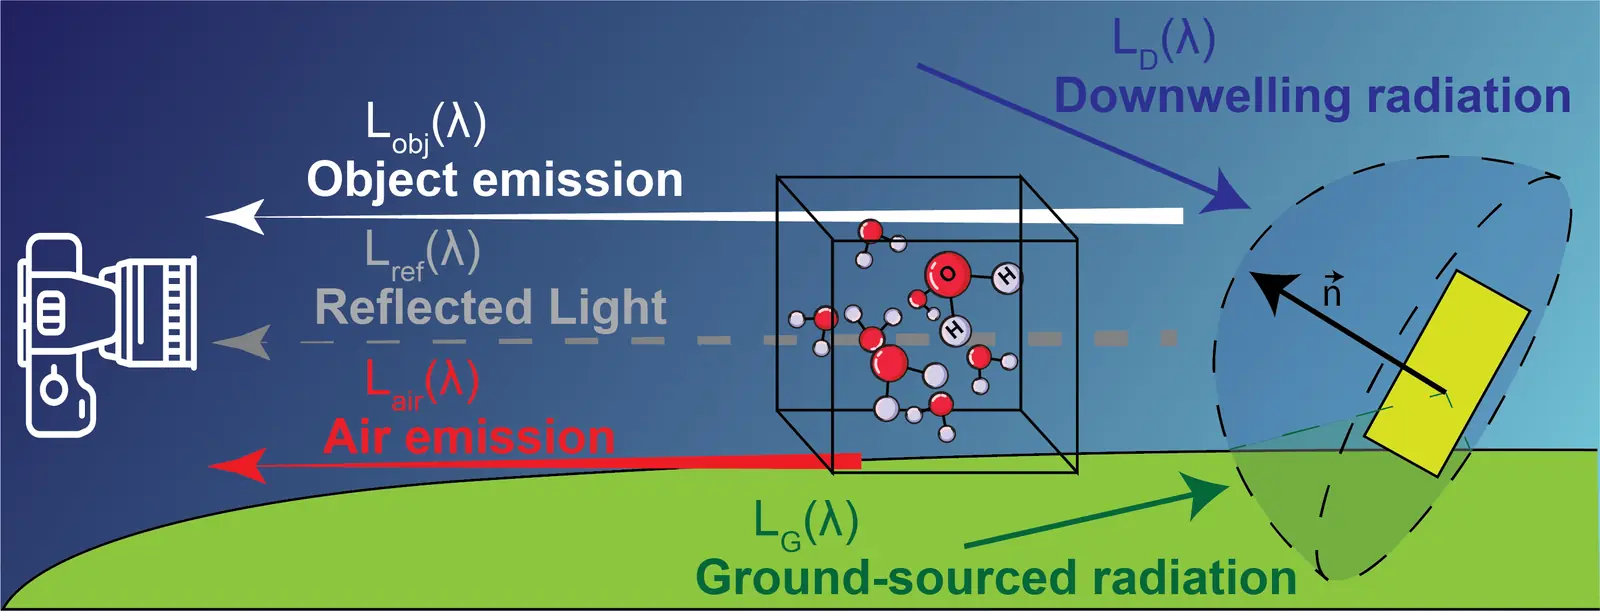
Figure 5. Radiance reaching a passive LWIR camera: object emission, reflected light, air emission, and downwelling and ground-sourced radiation. Reprinted from this paper, © 2026 IEEE. -
[3]
Learning Cross-Video Neural Representations for High-Quality Frame Interpolation
European Conference on Computer Vision (ECCV), 2022. *Equal contribution.
-
[4]
MS thesis, Washington University in St. Louis, 2021.
-
[5]
Adaptive Single-Photon Compressed Imaging Based on Constructing a Smart Threshold Matrix
Sensors 18(10):3449, 2018.
Education
-
Boston University
Sep 2022 – present
PhD, Electrical and Computer Engineering
-
Washington University in St. Louis
2021
MSc, Electrical and Systems Engineering
-
Nanchang University
2019
BEng, Communication Engineering
Earlier work

(a) Time-Resolved Particle Beam Microscopy
Learning-based scan-jitter correction for SEM, using a simulated forward model and Transformer models (cross deformable attention, Swin).
(b) CURE: Cross-Video Neural Representations for Frame Interpolation
A deep-learning model for video frame interpolation, which synthesizes a new frame from its two neighbors. It was the first video interpolation method based on neural fields and achieved state-of-the-art results on several benchmark datasets. Published at ECCV 2022. [3]

(c) Underwater Spectrophotometer for In-Situ Seawater COD Monitoring
An in-situ chemical oxygen demand (COD) sensor for long-term seawater monitoring, integrated into a buoy for coastal trials. The sensors worked underwater continuously for more than six months and recorded thousands of UV-Vis absorption spectra.

(d) Adaptive Single-Photon Compressed Imaging
A single-photon imaging system is a photon-counting single-pixel camera that images with compressed sensing (CS). We proposed a smart adaptive measurement matrix to improve CS reconstruction; experiments show it works with many algorithms and can modify any kind of measurement matrix. [5]
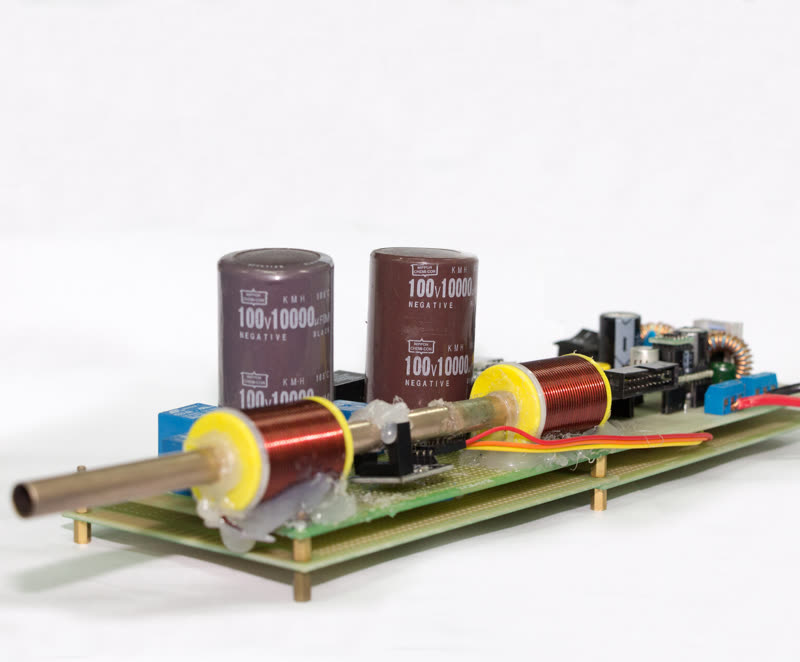
(e) Wireless Auto-Detection Electromagnetic Gun
A wireless electromagnetic gun; both the radio and the gun run on an STM32F103. The radio shows voltage and firing status and detects nearby objects, sending a fire signal over 2.4 GHz (nRF24L01). Two XL6009 converters step 12 V DC up to about 70 V, and the steel ball travels about 30 feet.
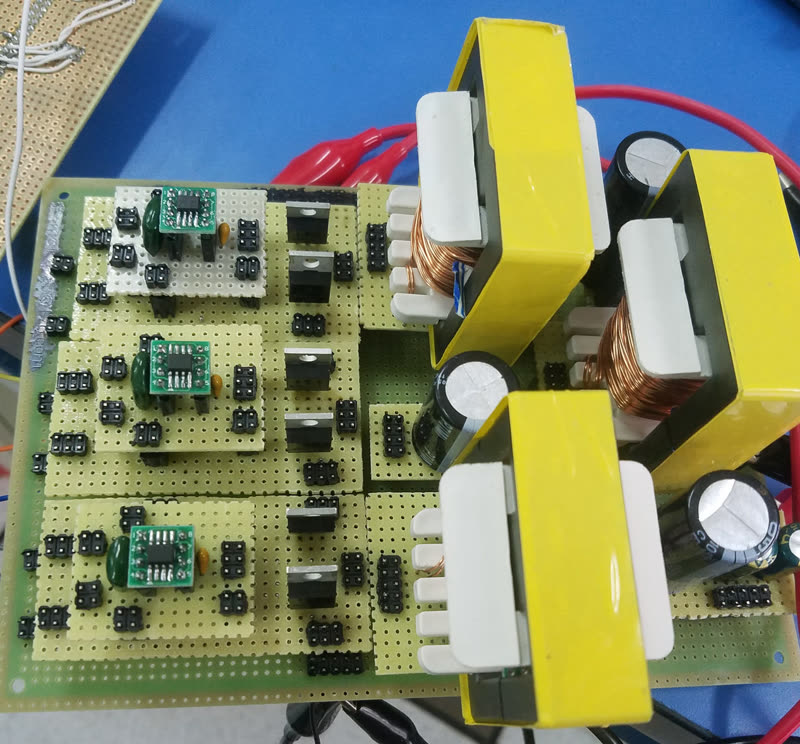
(f) Three-Phase DC-AC Converter
Converts 12 V DC to three-phase 24 V AC under STM32F103 control, with voltage regulation, phase regulation and over-current protection. Efficiency is above 90%, phase regulation lets two converters connect to a grid, and a PID loop regulates the output 100 times per second.
Photography